여태까지는 SRS 에서 뽑는 것이었다. 즉 다시 말해 뽑는 과정이 그저 i.i.d 하게 뽑는 것만 고려를 했었다. 하지만 이제는 i.i.d 하게 뽑기보다는 조금 다르게 뽑아줘서 추정량에 대한 분산을 줄여줘보겠습니다.
정확하게 그래서 어떤 얘기를 하느냐, 우선은 예시로 X ˉ \bar X X ˉ
θ = E [ X ] \theta = \mathbb{E}[X] θ = E [ X ] X ˉ \bar X X ˉ X ˉ \bar X X ˉ X ˉ \bar X X ˉ
MSE = E [ ( X ˉ − θ ) 2 ] → V a r ( X ˉ ) = V a r ( X ) n \text{MSE} = \mathbb{E}\left[ \left( \bar X - \theta
\right)^2 \right] \rightarrow \mathrm{Var}(\bar X) = \frac{\mathrm{Var}(X)}{n} MSE = E [ ( X ˉ − θ ) 2 ] → Var ( X ˉ ) = n Var ( X ) 그저 i.i.d 하게 뽑는 것만 고려한다면 샘플 개수인 n n n
Antithetic Variables 예전에 분산을 줄이기 위해서 사용되었던 방법이며, Negative 하게 뽑아서 Negative Correlation 인 점을 활용합니다.
X 1 , X 2 X_1, X_2 X 1 , X 2
V a r ( X 1 + X 2 2 ) = 1 4 [ V a r ( X 1 ) + V a r ( X 2 ) + 2 ⋅ C o v ( X 1 , X 2 ) ] \mathrm{Var}\left(\frac{X_1 + X_2}{2} \right) = \frac 1 4 \left[ \mathrm{Var}(X_1) + \mathrm{Var}(X_2) + 2 \cdot \mathrm{Cov}(X_1, X_2)\right] Var ( 2 X 1 + X 2 ) = 4 1 [ Var ( X 1 ) + Var ( X 2 ) + 2 ⋅ Cov ( X 1 , X 2 ) ] 하지만 i.i.d 하기 때문에 당연하게도 공분산이 0 0 0
V a r ( X 1 + X 2 2 ) = 1 4 [ V a r ( X 1 ) + V a r ( X 2 ) ] \mathrm{Var}\left(\frac{X_1 + X_2}{2} \right) = \frac 1 4 \left[ \mathrm{Var}(X_1) + \mathrm{Var}(X_2) \right] Var ( 2 X 1 + X 2 ) = 4 1 [ Var ( X 1 ) + Var ( X 2 ) ] 여기에서 분산을 그러면 어떻게 줄이냐, 바로 C o v ( X 1 , X 2 ) \mathrm{Cov}(X_1, X_2) Cov ( X 1 , X 2 ) X 1 = h ( U 1 , ⋯ , U m ) X_1 = h(U_1, \cdots, U_m) X 1 = h ( U 1 , ⋯ , U m ) X 2 = h ( 1 − U 1 , 1 − U 2 , ⋯ , 1 − U m ) X_2 = h\left(1-U_1, 1-U_2, \cdots, 1-U_m
\right) X 2 = h ( 1 − U 1 , 1 − U 2 , ⋯ , 1 − U m )
이렇게 진행한다면 C o v ( X 1 , X 2 ) < 0 \mathrm{Cov}(X_1, X_2) < 0 Cov ( X 1 , X 2 ) < 0
V a r ( X 1 + X 2 2 ) = 1 4 [ V a r ( X 1 ) + V a r ( X 2 ) + 2 ⋅ C o v ( X 1 , X 2 ) ] < 1 4 [ V a r ( X 1 ) + V a r ( X 2 ) ] \begin{aligned}
\mathrm{Var}\left(\frac{X_1 + X_2}{2} \right) &= \frac 1 4 \left[ \mathrm{Var}(X_1) + \mathrm{Var}(X_2) + 2 \cdot \mathrm{Cov}(X_1, X_2)\right] \\&< \frac 1 4 \left[ \mathrm{Var}(X_1) + \mathrm{Var}(X_2) \right]\end{aligned} Var ( 2 X 1 + X 2 ) = 4 1 [ Var ( X 1 ) + Var ( X 2 ) + 2 ⋅ Cov ( X 1 , X 2 ) ] < 4 1 [ Var ( X 1 ) + Var ( X 2 ) ]
Example 1 θ = E [ e U ] \theta = \mathbb{E}\left[e^{U} \right] θ = E [ e U ]
V a r ( e U ) = E [ ( e U ) 2 ] − ( E [ e U ] ) 2 = ∫ 0 1 e 2 u d u − ( [ e x ] x = 0 x = 1 ) 2 = [ 1 2 ⋅ e 2 x ] x = 0 x = 1 − ( e − 1 ) 2 = e 2 − 1 2 − ( e − 1 ) 2 ≈ 0.242 C o v ( e U , e 1 − U ) = E [ e U ⋅ e 1 − U ] − E [ e U ] ⋅ E [ e 1 − U ] = E [ e U ⋅ e 1 ⋅ e − U ] − ( e − 1 ) ⋅ ∫ 0 1 e 1 − u d u = E [ e ] − ( e − 1 ) ⋅ e ⋅ [ − e − x ] x = 0 x = 1 = e − ( e − 1 ) ⋅ e ⋅ ( 1 − e − 1 ) = e − ( e − 1 ) ⋅ e ⋅ ( e − 1 ) e = e − ( e − 1 ) 2 ≈ − 0.234 \begin{aligned}
\mathrm{Var}\left(e^U\right) &= \mathbb{E}\left[\left(e^{U}\right)^2 \right] - \left(\mathbb{E}\left[e^U \right]\right)^2
= \int_0^1 e^{2u} du - \left(\left[ e^x\right]_{x=0}^{x=1} \right)^2
\\&= \left[\frac 1 2 \cdot e^{2x} \right]_{x=0}^{x=1} - \left( e - 1 \right)^2 = \frac{e^2 - 1}{2} - \left( e - 1 \right)^2
\approx 0.242
\\~\\
\mathrm{Cov}\left(e^U, e^{1-U} \right) &= \mathbb{E}\left[e^U \cdot e^{1-U} \right] - \mathbb{E}\left[e^U \right]\cdot \mathbb{E}\left[e^{1-U}\right]
\\&= \mathbb{E}\left[ e^U \cdot e^1 \cdot e^{-U} \right] - (e-1)\cdot \int_0^1 e^{1-u} du
\\&= \mathbb{E}\left[e \right] -
(e-1) \cdot e \cdot \left[-e^{-x} \right]_{x=0}^{x=1}
\\&= e - (e-1)\cdot e \cdot (1-e^{-1})
\\&= e - (e-1) \cdot e \cdot \frac{(e-1)}{e}
\\&= e - (e-1)^2 \approx -0.234
\end{aligned} Var ( e U ) Cov ( e U , e 1 − U ) = E [ ( e U ) 2 ] − ( E [ e U ] ) 2 = ∫ 0 1 e 2 u d u − ( [ e x ] x = 0 x = 1 ) 2 = [ 2 1 ⋅ e 2 x ] x = 0 x = 1 − ( e − 1 ) 2 = 2 e 2 − 1 − ( e − 1 ) 2 ≈ 0.242 = E [ e U ⋅ e 1 − U ] − E [ e U ] ⋅ E [ e 1 − U ] = E [ e U ⋅ e 1 ⋅ e − U ] − ( e − 1 ) ⋅ ∫ 0 1 e 1 − u d u = E [ e ] − ( e − 1 ) ⋅ e ⋅ [ − e − x ] x = 0 x = 1 = e − ( e − 1 ) ⋅ e ⋅ ( 1 − e − 1 ) = e − ( e − 1 ) ⋅ e ⋅ e ( e − 1 ) = e − ( e − 1 ) 2 ≈ − 0.234 일반적인 Monte-Carlo Estimate 방법에서는 그저 U 1 , U 2 , ⋯ , U n U_1, U_2, \cdots, U_n U 1 , U 2 , ⋯ , U n e U i e^{U_i} e U i 1 n ∑ i = 1 n e U i \frac{1}{n}\sum_{i=1}^n e^{U_i} n 1 ∑ i = 1 n e U i
2 2 2
V a r ( e U 1 + e U 2 2 ) = 1 2 ⋅ V a r ( e U ) ≈ 0.121 \mathrm{Var}\left(\frac{e^{U_1} + e^{U_2}}{2} \right) = \frac{1}{2} \cdot \mathrm{Var}(e^{U}) \approx 0.121 Var ( 2 e U 1 + e U 2 ) = 2 1 ⋅ Var ( e U ) ≈ 0.121 이제는 Antithetic Variable 를 활용해보겠습니다.
똑같이 U 1 , ( 1 − U 1 ) U_1, (1-U_1) U 1 , ( 1 − U 1 ) e U 1 + e 1 − U 1 2 \frac{e^{U_1} + e^{1-U_1}}{2} 2 e U 1 + e 1 − U 1
V a r ( e U 1 + e 1 − U 1 2 ) = 1 4 ⋅ [ V a r ( e U 1 ) + V a r ( e 1 − U 1 ) + 2 ⋅ C o v ( e U 1 , e 1 − U 1 ) ] = 1 2 ⋅ [ V a r ( e U 1 ) + C o v ( e U 1 , e 1 − U 1 ) ] = 1 2 ⋅ [ 0.242 − 0.234 ] ≈ 0.004 \begin{aligned}
\mathrm{Var}\left(\frac{e^{U_1} + e^{1 - U_1}}{2} \right) &= \frac{1}{4} \cdot \left[
\mathrm{Var}\left(e^{U_1} \right) + \mathrm{Var}\left(e^{1-U_1}\right) + 2 \cdot \mathrm{Cov}\left(e^{U_1}, e^{1-U_1} \right)
\right]
\\&= \frac{1}{2}\cdot \left[\mathrm{Var}\left(e^{U_1} \right) + \mathrm{Cov}\left(e^{U_1}, e^{1-U_1} \right) \right]
\\&= \frac 1 2 \cdot \left[
0.242 - 0.234
\right] \approx 0.004
\end{aligned} Var ( 2 e U 1 + e 1 − U 1 ) = 4 1 ⋅ [ Var ( e U 1 ) + Var ( e 1 − U 1 ) + 2 ⋅ Cov ( e U 1 , e 1 − U 1 ) ] = 2 1 ⋅ [ Var ( e U 1 ) + Cov ( e U 1 , e 1 − U 1 ) ] = 2 1 ⋅ [ 0.242 − 0.234 ] ≈ 0.004 두 분산을 비교하면, 확실하게 이득을 본 모습입니다.
사실은 Monte-Carlo Estimate 에서 2 2 2 1 1 1
이것에 대한 실제 코드와 함께 확인해보겠습니다.
rm(list=ls())
N = 10000
mc_estimator = exp(runif(N))
u_vals = runif(N / 2)
antithetic_estimator = c((exp(u_vals) + exp(1 - u_vals)) / 2)
cat("MC Estimator Mean : ", mean(mc_estimator), "Var : ", var(mc_estimator),
    "\nAntithetic Estimator : ", mean(antithetic_estimator), "Var : ", var(antithetic_estimator))
Example 2 원에서 π \pi π ( U 1 , U 2 ) (U_1, U_2) ( U 1 , U 2 ) N N N 1 ( U 1 2 + U 2 2 ≤ 1 ) \mathbb{1}\left(U_1^2 + U_2^2 \le 1 \right) 1 ( U 1 2 + U 2 2 ≤ 1 ) ( 1 − U 1 , 1 − U 2 ) (1-U_1, 1-U_2) ( 1 − U 1 , 1 − U 2 )
rm(list=ls())
# MC-Estimate
N = 10000
u1_vals = runif(N)
u2_vals = runif(N)
circle_indicator = ifelse(u1_vals ** 2 + u2_vals ** 2 <= 1, 4, 0)
mc_est = mean(circle_indicator)
mc_var = var(circle_indicator)
mc_SE = sqrt(mc_var / N)

# Antithetic Estimator
M = N / 2
u1_vals = runif(M)
u2_vals = runif(M)
u1_u2_est = ifelse(u1_vals ** 2 + u2_vals ** 2 <= 1, 4, 0)
anti_u1_u2_est = ifelse((1 - u1_vals) ** 2 + (1 - u2_vals) ** 2 <= 1, 4, 0)

anti_circle_est = (u1_u2_est + anti_u1_u2_est) / 2

anti_est = mean(anti_circle_est)
anti_var = var(anti_circle_est)
anti_SE = sqrt(anti_var / M)

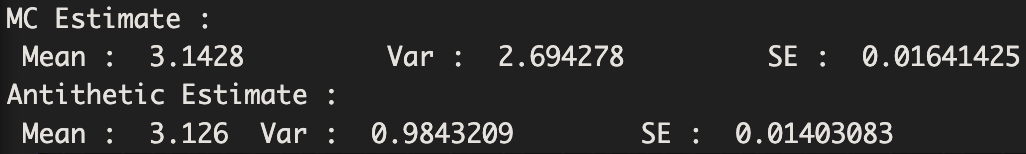
cat("MC Estimate :\n", "Mean : ", mc_est, "\tVar : ", mc_var, "\tSE : ", mc_SE,
    "\nAntithetic Estimate :\n", "Mean : ", anti_est, "\tVar : ", anti_var, "\tSE : ", anti_SE)
드라마틱한 감소는 없지만, 표준오차에 대한 감소가 있기는 합니다.
Control Variables 똑같이 θ = E [ X ] \theta = \mathbb{E}\left[X\right] θ = E [ X ] Y Y Y
X + c ( Y − μ Y ) X + c\left(Y - \mu_Y\right) X + c ( Y − μ Y ) E [ X + c ( Y − μ Y ) ] = E [ X ] = θ \mathbb{E}\left[X + c\left(Y - \mu_Y\right) \right] = \mathbb{E}[X] = \theta E [ X + c ( Y − μ Y ) ] = E [ X ] = θ V a r ( X + c ( Y − μ Y ) ) = V a r ( X + c Y ) = V a r ( X ) + c 2 ⋅ V a r ( Y ) + 2 c ⋅ C o v ( X , Y ) \mathrm{Var}\left(X + c\left(Y - \mu_Y\right) \right) = \mathrm{Var}\left(X + cY \right) = \mathrm{Var}(X) + c^2 \cdot \mathrm{Var}(Y) + 2 c \cdot \mathrm{Cov}(X, Y) Var ( X + c ( Y − μ Y ) ) = Var ( X + c Y ) = Var ( X ) + c 2 ⋅ Var ( Y ) + 2 c ⋅ Cov ( X , Y ) 분산 부분을 살피면, 저희는 c c c
c ∗ : = arg min c [ V a r ( X ) + c 2 ⋅ V a r ( Y ) + 2 c ⋅ C o v ( X , Y ) ] c^* := \argmin_c\left[
\mathrm{Var}(X) + c^2 \cdot \mathrm{Var}(Y) + 2 c \cdot \mathrm{Cov}(X, Y)
\right] c ∗ := c arg min [ Var ( X ) + c 2 ⋅ Var ( Y ) + 2 c ⋅ Cov ( X , Y ) ] 이것을 구하기 위해서는 c c c
2 c ⋅ V a r ( Y ) + 2 ⋅ C o v ( X , Y ) = set 0 c ∗ = − C o v ( X , Y ) V a r ( Y ) \begin{aligned}
2c \cdot \mathrm{Var}(Y) &+ 2 \cdot \mathrm{Cov}(X, Y) \stackrel{\text{set}}{=} 0
\\
c^* & = -\frac{\mathrm{Cov}(X, Y)}{\mathrm{Var}(Y)}
\end{aligned} 2 c ⋅ Var ( Y ) c ∗ + 2 ⋅ Cov ( X , Y ) = set 0 = − Var ( Y ) Cov ( X , Y ) c c c
V a r ( X − C o v ( X , Y ) V a r ( Y ) ⋅ ( Y − μ Y ) ) = V a r ( X ) + [ C o v ( X , Y ) V a r ( Y ) ] 2 ⋅ V a r ( Y ) − 2 ⋅ [ C o v ( X , Y ) V a r ( Y ) ] ⋅ C o v ( X , Y ) = V a r ( X ) − [ C o v ( X , Y ) ] 2 V a r ( Y ) = V a r ( X ) − ρ 2 ⋅ V a r ( X ) = V a r ( X ) ⋅ ( 1 − ρ 2 ) ≤ V a r ( X ) \begin{aligned}
\mathrm{Var}\left(X - \frac{\mathrm{Cov}(X, Y)}{\mathrm{Var}(Y)} \cdot \left(Y - \mu_Y\right) \right)
&=\mathrm{Var}(X) + \left[\frac{\mathrm{Cov}(X,Y)}{\mathrm{Var}(Y)}\right]^2 \cdot \mathrm{Var}(Y)
\\& - 2 \cdot \left[\frac{\mathrm{Cov}(X,Y)}{\mathrm{Var}(Y)} \right] \cdot \mathrm{Cov}(X, Y)
\\ & = \mathrm{Var}(X) - \frac{\left[\mathrm{Cov}(X,Y) \right]^2}{\mathrm{Var}(Y)}
\\&= \mathrm{Var}(X) - \rho^2 \cdot \mathrm{Var}(X)
\\&= \mathrm{Var}(X) \cdot \left( 1 - \rho^2\right) \le \mathrm{Var}(X)
\end{aligned} Var ( X − Var ( Y ) Cov ( X , Y ) ⋅ ( Y − μ Y ) ) = Var ( X ) + [ Var ( Y ) Cov ( X , Y ) ] 2 ⋅ Var ( Y ) − 2 ⋅ [ Var ( Y ) Cov ( X , Y ) ] ⋅ Cov ( X , Y ) = Var ( X ) − Var ( Y ) [ Cov ( X , Y ) ] 2 = Var ( X ) − ρ 2 ⋅ Var ( X ) = Var ( X ) ⋅ ( 1 − ρ 2 ) ≤ Var ( X )
Example 3 이전과 똑같은 예시를 가지겠습니다. θ = E [ e U ] \theta = \mathbb{E}\left[e^{U} \right] θ = E [ e U ] Y = U Y = U Y = U
rm(list=ls())
N = 10000
u_vals = runif(N)
exp_u_vals = exp(u_vals)
c = - cov(u_vals, exp_u_vals) / var(u_vals)
mu_y = 0.5
control_estimators = exp_u_vals + c * (u_vals - mu_y)
mc_mean = mean(exp_u_vals)
mc_var = var(exp_u_vals)
mc_SE = sqrt(mc_var / N)
control_mean = mean(control_estimators)
control_var = var(control_estimators)
control_SE = sqrt(control_var / N)
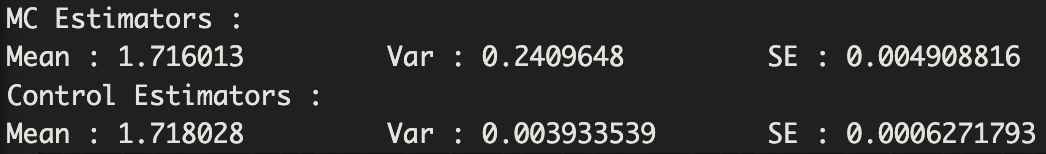
cat("MC Estimators :\nMean :", mc_mean, "\tVar :", mc_var, "\tSE :", mc_SE,
    "\nControl Estimators : \nMean :", control_mean, "\tVar :", control_var, "\tSE :", control_SE)
Conditioning EVVE 를 활용하면 다음과 같이 분산을 적어줄 수가 있습니다.
V a r ( X ) = E [ V a r ( X ∣ Y ) ] + V a r ( E [ X ∣ Y ] ) ≥ V a r ( E [ X ∣ Y ] ) \begin{aligned}
\mathrm{Var}(X) & =\mathbb E[\mathrm{Var}(X \mid Y)]+\mathrm{Var}(\mathbb E[X \mid Y]) \\
& \geq \mathrm{Var}(\mathbb E[X \mid Y])
\end{aligned} Var ( X ) = E [ Var ( X ∣ Y )] + Var ( E [ X ∣ Y ]) ≥ Var ( E [ X ∣ Y ]) 이 점을 활용해서 X X X E [ X ∣ Y ] \mathbb{E}\left[X \mid Y\right] E [ X ∣ Y ]
E [ E [ X ∣ Y ] ] = E [ X ] = θ \mathbb{E}\left[\mathbb{E}\left[X \mid Y \right] \right] = \mathbb{E}\left[ X \right] = \theta E [ E [ X ∣ Y ] ] = E [ X ] = θ V a r ( E [ X ∣ Y ] ) ≤ V a r ( X ) \mathrm{Var}\left(\mathbb{E}[X \mid Y] \right) \le \mathrm{Var}(X) Var ( E [ X ∣ Y ] ) ≤ Var ( X ) 그렇기에 저희는 사실은 추정량을 E [ X ∣ Y ] = g ( Y ) \mathbb{E}[X \mid Y] = g(Y) E [ X ∣ Y ] = g ( Y )
Example 4 ( U 1 , U 2 ) ∼ Unif ( [ 0 , 1 ] 2 ) \left(U_1, U_2\right) \sim \operatorname{Unif}\left([0,1]^2\right) ( U 1 , U 2 ) ∼ Unif ( [ 0 , 1 ] 2 ) X = 4 ⋅ 1 { U 1 2 + U 2 2 ≤ 1 } X=4 \cdot \mathbf{1}\left\{U_1^2+U_2^2 \leq 1\right\} X = 4 ⋅ 1 { U 1 2 + U 2 2 ≤ 1 } E [ X ] = π \mathbb{E}[X] = \pi E [ X ] = π
기본적인 MC-Estimate 을 사용한다면 분산은 다음과 같이 나옵니다.
Var ( X ) = 16 Var ( I ) = 16 p ( 1 − p ) = 16 ( π 4 ) ( 1 − π 4 ) = 4 π − π 2 \operatorname{Var}(X)=16 \operatorname{Var}(I)=16 p(1-p)=16\left(\frac{\pi}{4}\right)\left(1-\frac{\pi}{4}\right)=4 \pi-\pi^2 Var ( X ) = 16 Var ( I ) = 16 p ( 1 − p ) = 16 ( 4 π ) ( 1 − 4 π ) = 4 π − π 2 대신에 다음과 같은 Condition 을 활용하겠습니다.
E [ X ∣ U 1 = u 1 ] = 4 ⋅ P ( U 2 ≤ 1 − u 1 2 ) = 4 ⋅ 1 − u 1 2 \mathbb{E}\left[X \mid U_1=u_1\right]=4\cdot \mathrm{P}\left(U_2 \leq \sqrt{1-u_1^2}\right)=4 \cdot \sqrt{1-u_1^2} E [ X ∣ U 1 = u 1 ] = 4 ⋅ P ( U 2 ≤ 1 − u 1 2 ) = 4 ⋅ 1 − u 1 2 그러면 이를 활용해서 g ( U 1 ) = 4 ⋅ 1 − U 1 2 g(U_1) = 4\cdot \sqrt{1-U_1^2} g ( U 1 ) = 4 ⋅ 1 − U 1 2 U 2 U_2 U 2
E [ g ( U ) ] = 4 ∫ 0 1 1 − u 2 d u = 4 ⋅ π 4 = π \mathbb{E}[g(U)]=4 \int_0^1 \sqrt{1-u^2} d u=4 \cdot \frac{\pi}{4}=\pi E [ g ( U )] = 4 ∫ 0 1 1 − u 2 d u = 4 ⋅ 4 π = π E [ g ( U ) 2 ] = 16 ∫ 0 1 ( 1 − u 2 ) d u = 16 [ u − u 3 3 ] 0 1 = 16 ( 1 − 1 3 ) = 32 3 \mathbb{E}\left[g(U)^2\right]=16 \int_0^1\left(1-u^2\right) d u=16\left[u-\frac{u^3}{3}\right]_0^1=16\left(1-\frac{1}{3}\right)=\frac{32}{3} E [ g ( U ) 2 ] = 16 ∫ 0 1 ( 1 − u 2 ) d u = 16 [ u − 3 u 3 ] 0 1 = 16 ( 1 − 3 1 ) = 3 32 V a r ( E [ X ∣ U 1 ] ) = E [ g ( U ) 2 ] − ( E [ g ( U ) ] ) 2 = 32 3 − π 2 \mathrm{Var}\left(\mathbb{E}\left[X \mid U_1 \right]\right) = \mathbb{E}\left[g(U)^2 \right] - \left(\mathbb{E}\left[g(U) \right]\right)^2 = \frac{32}{3} - \pi^2 Var ( E [ X ∣ U 1 ] ) = E [ g ( U ) 2 ] − ( E [ g ( U ) ] ) 2 = 3 32 − π 2 위의 것과 비교하면 4 π > 32 / 3 4\pi > 32/3 4 π > 32/3
Stratified Sampling Conditioning 개념을 이제는 Group 들로 나누어서 가는 개념입니다. 즉 만약에 Y Y Y p i = P r { Y = y i } , i = 1 , ⋯ , k p_i = \mathrm{Pr}\{Y=y_i\}, i = 1, \cdots, k p i = Pr { Y = y i } , i = 1 , ⋯ , k
E [ X ] = E [ E [ X ∣ Y ] ] = ∑ i = 1 k E [ X ∣ Y = y i ] ⋅ p i \mathbb{E}[X] = \mathbb{E}[\mathbb{E}[X\mid Y]] = \sum_{i=1}^k \mathbb{E}\left[X \mid Y = y_i \right] \cdot p_i E [ X ] = E [ E [ X ∣ Y ]] = i = 1 ∑ k E [ X ∣ Y = y i ] ⋅ p i 저희의 최종 추정량은 그럼 θ ^ = ∑ i = 1 k p i X ˉ i \hat \theta = \sum_{i=1}^k p_i \bar X_i θ ^ = ∑ i = 1 k p i X ˉ i
Var ( θ ^ ) = ∑ i = 1 k p i 2 n i Var ( X ∣ Y = y i ) = 1 n ∑ i = 1 k p i Var ( X ∣ Y = y i ) ( if we let n i = n p i ) = 1 n E [ Var ( X ∣ Y ) ] ≤ 1 n Var ( X ) \begin{aligned}\operatorname{Var}(\hat{\theta}) & =\sum_{i=1}^k \frac{p_i^2}{n_i} \operatorname{Var}\left(X \mid Y=y_i\right) \\& =\frac{1}{n} \sum_{i=1}^k p_i \operatorname{Var}\left(X \mid Y=y_i\right) \quad\left(\text { if we let } n_i=n p_i\right) \\& =\frac{1}{n} E[\operatorname{Var}(X \mid Y)] \leq \frac{1}{n} \operatorname{Var}(X)\end{aligned} Var ( θ ^ ) = i = 1 ∑ k n i p i 2 Var ( X ∣ Y = y i ) = n 1 i = 1 ∑ k p i Var ( X ∣ Y = y i ) ( if we let n i = n p i ) = n 1 E [ Var ( X ∣ Y )] ≤ n 1 Var ( X )
Importance Sampling 샘플링하기 어려운 것들을 더 쉽게 샘플링하는 방법입니다. 예시로 θ = E f [ h ( X ) ] = ∫ h ( x ) f ( x ) d x \theta = \mathbb{E}_f[h(X)] = \int h(x) f(x) dx θ = E f [ h ( X )] = ∫ h ( x ) f ( x ) d x f f f h ( x ) h(x) h ( x ) g g g
θ = E f [ h ( X ) ] = ∫ h ( x ) f ( x ) d x = ∫ h ( x ) g ( x ) g ( x ) f ( x ) d x = ∫ g ( x ) h ( x ) g ( x ) f ( x ) d x = E g [ h ( x ) g ( x ) ⋅ f ( x ) ] ≈ 1 n ∑ h ( x i ) f ( x i ) g ( x i ) \begin{aligned}
\theta &= \mathbb{E}_f[h(X)]= \int h(x) f(x) dx = \int h(x) \frac{g(x)}{g(x)} f(x) dx
\\&= \int g(x) \frac{h(x)}{g(x)} f(x) dx = \mathbb{E}_g\left[\frac{h(x)}{g(x)} \cdot f(x)\right] \approx \frac{1}{n}\sum \frac{h(x_i)f(x_i)}{g(x_i)}
\end{aligned} θ = E f [ h ( X )] = ∫ h ( x ) f ( x ) d x = ∫ h ( x ) g ( x ) g ( x ) f ( x ) d x = ∫ g ( x ) g ( x ) h ( x ) f ( x ) d x = E g [ g ( x ) h ( x ) ⋅ f ( x ) ] ≈ n 1 ∑ g ( x i ) h ( x i ) f ( x i )